

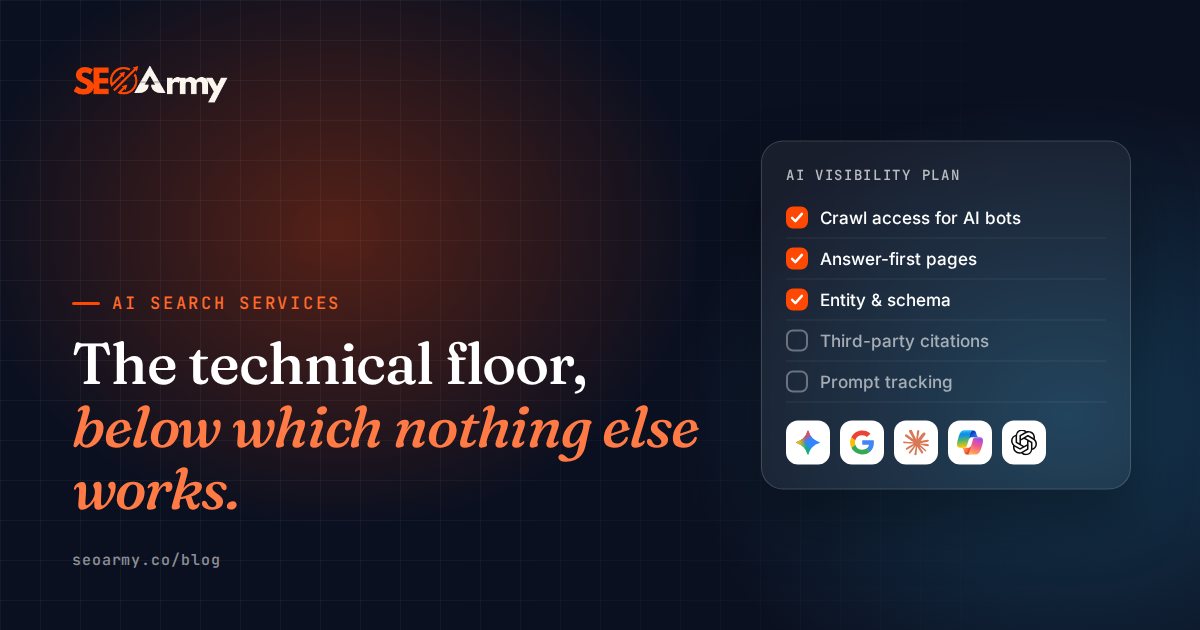
Before any content or entity work matters, a system has to be able to reach your pages and read them. That sounds trivial and is a genuine cause of invisibility often enough to be worth checking first, because it is cheap to check and expensive to assume.
The floor
Reachability
Robots.txt allows the crawlers you want. No CDN or bot-protection rule silently blocking them. No geo-restrictions on regions the crawlers operate from.
Rendering
Content present in the HTML rather than assembled client-side. Some AI crawlers render JavaScript inconsistently or not at all, so content that appears only after execution may simply not exist to them.
Speed and stability
Slow or intermittently failing pages get fetched less reliably. A page timing out during a crawl is indistinguishable from a page that does not exist.
Stable URLs
Content moving between URLs without redirects breaks accumulated understanding, and repeated moves make a site harder to model.
The checks worth running
- Fetch a key page with JavaScript disabled. Is the substance there?
- Grep your server logs for the documented AI crawler user agents. Are they arriving, and what status codes are they receiving?
- Check your CDN or WAF rules for bot categories that may include AI crawlers by default.
- Validate every JSON-LD block. Invalid markup is discarded silently.
- Confirm content is not gated behind interaction — accordions and tabs that load on click.
Want a baseline before deciding anything?
Our free AI Visibility Report gives you one, with no obligation.
Request one →The crawlers to look for in your logs
Each major operator documents its user agents, and most separate training, search indexing and user-triggered fetching. OpenAI lists GPTBot, OAI-SearchBot and ChatGPT-User. Anthropic lists ClaudeBot, Claude-SearchBot and Claude-User. Perplexity lists PerplexityBot and Perplexity-User. Google uses Googlebot for search (including AI Overviews) and a separate Google-Extended robots.txt token to control use of content for Gemini models.
Search your access logs for each name and look at the response codes. A run of 403s or 429s against one operator's search crawler is the signature of a firewall rule, and it explains a lot of “why are we never cited in X” questions.
Why this gets missed
These are infrastructure settings, usually owned by a different team from the one worrying about visibility. A bot-protection rule added for security reasons can remove a site from AI answers entirely, and nobody connects the two events because they are months apart and in different systems.
It is worth asking the infrastructure team directly rather than inferring from the outside. Ten minutes of conversation frequently explains months of unexplained invisibility.
Rendering, tested properly
The quickest rendering test is to view the raw HTML of a key page (not the inspector, which shows the rendered DOM) and search for a distinctive sentence from the main content. If it is not there, the content is assembled by JavaScript.
Google renders JavaScript reliably, so this may never have hurt your rankings. Many AI fetchers are simpler and read the HTML they receive. Server-side rendering or static generation for important pages removes the question entirely, and it usually makes pages faster for people too.
Faster discovery
Being crawlable is the floor; being discovered quickly is the next step up. Keep an accurate XML sitemap with real lastmod dates, submit it in Google Search Console and Bing Webmaster Tools, and implement IndexNow so Bing and other participating engines hear about changes as they happen.
Because Copilot, and several other assistants, draw on Bing's index, Bing Webmaster Tools deserves more attention than most teams give it. It also now reports how often your pages are cited in AI answers, which is a useful check that the technical floor is holding.
Frequently asked questions
What technical requirements matter for AI search?
Crawler access unblocked by robots.txt, CDN or WAF rules; content present in HTML rather than assembled client-side; adequate speed and stability; stable URLs; and valid structured data.
Does JavaScript rendering affect AI search visibility?
It can. Some AI crawlers render JavaScript inconsistently or not at all, so content that only appears after execution may be invisible to them even though it is fine for traditional search.
Why might a site be invisible in AI search despite good content?
Frequently an infrastructure setting: a bot-protection or CDN rule blocking AI crawlers, added for security reasons by a different team months earlier. It is worth asking directly rather than inferring.
Does Google-Extended affect AI Overviews?
No. Google-Extended controls whether content is used for Gemini model training and grounding in some Google AI products; AI Overviews are part of Search and use Googlebot.
Do AI crawlers respect robots.txt?
The major operators say their crawlers do. User-triggered fetchers can behave differently because a person requested the page, so check each operator's documentation.
Sources & further reading
- Introduction to robots.txt — Google Search Central
- Overview of OpenAI crawlers — OpenAI Platform docs
- Perplexity crawlers — Perplexity docs
- Does Anthropic crawl data from the web, and how can site owners block the crawler? — Claude Help Center
- Google's common crawlers (incl. Google-Extended) — Google for Developers
- Bing Webmaster Guidelines — Microsoft Bing
- IndexNow protocol — IndexNow.org
Sully has built search-driven growth for businesses across more than 20 industries and was an early practitioner of AI search visibility, helping clients get cited by ChatGPT and Perplexity before most agencies were paying attention. Sully reviews the strategy behind every SEOArmy article. More about Sully →
Keep reading
 GuideAI crawlers and robots.txt: what to allow
- Structured data for AI search
 GuideThe AI search optimization checklist